PrismML Releases Ternary Bonsai 2 27B: A 5.9 GB Apache 2.0 Model Retaining 98.2% of Qwen3.8 27B Performance
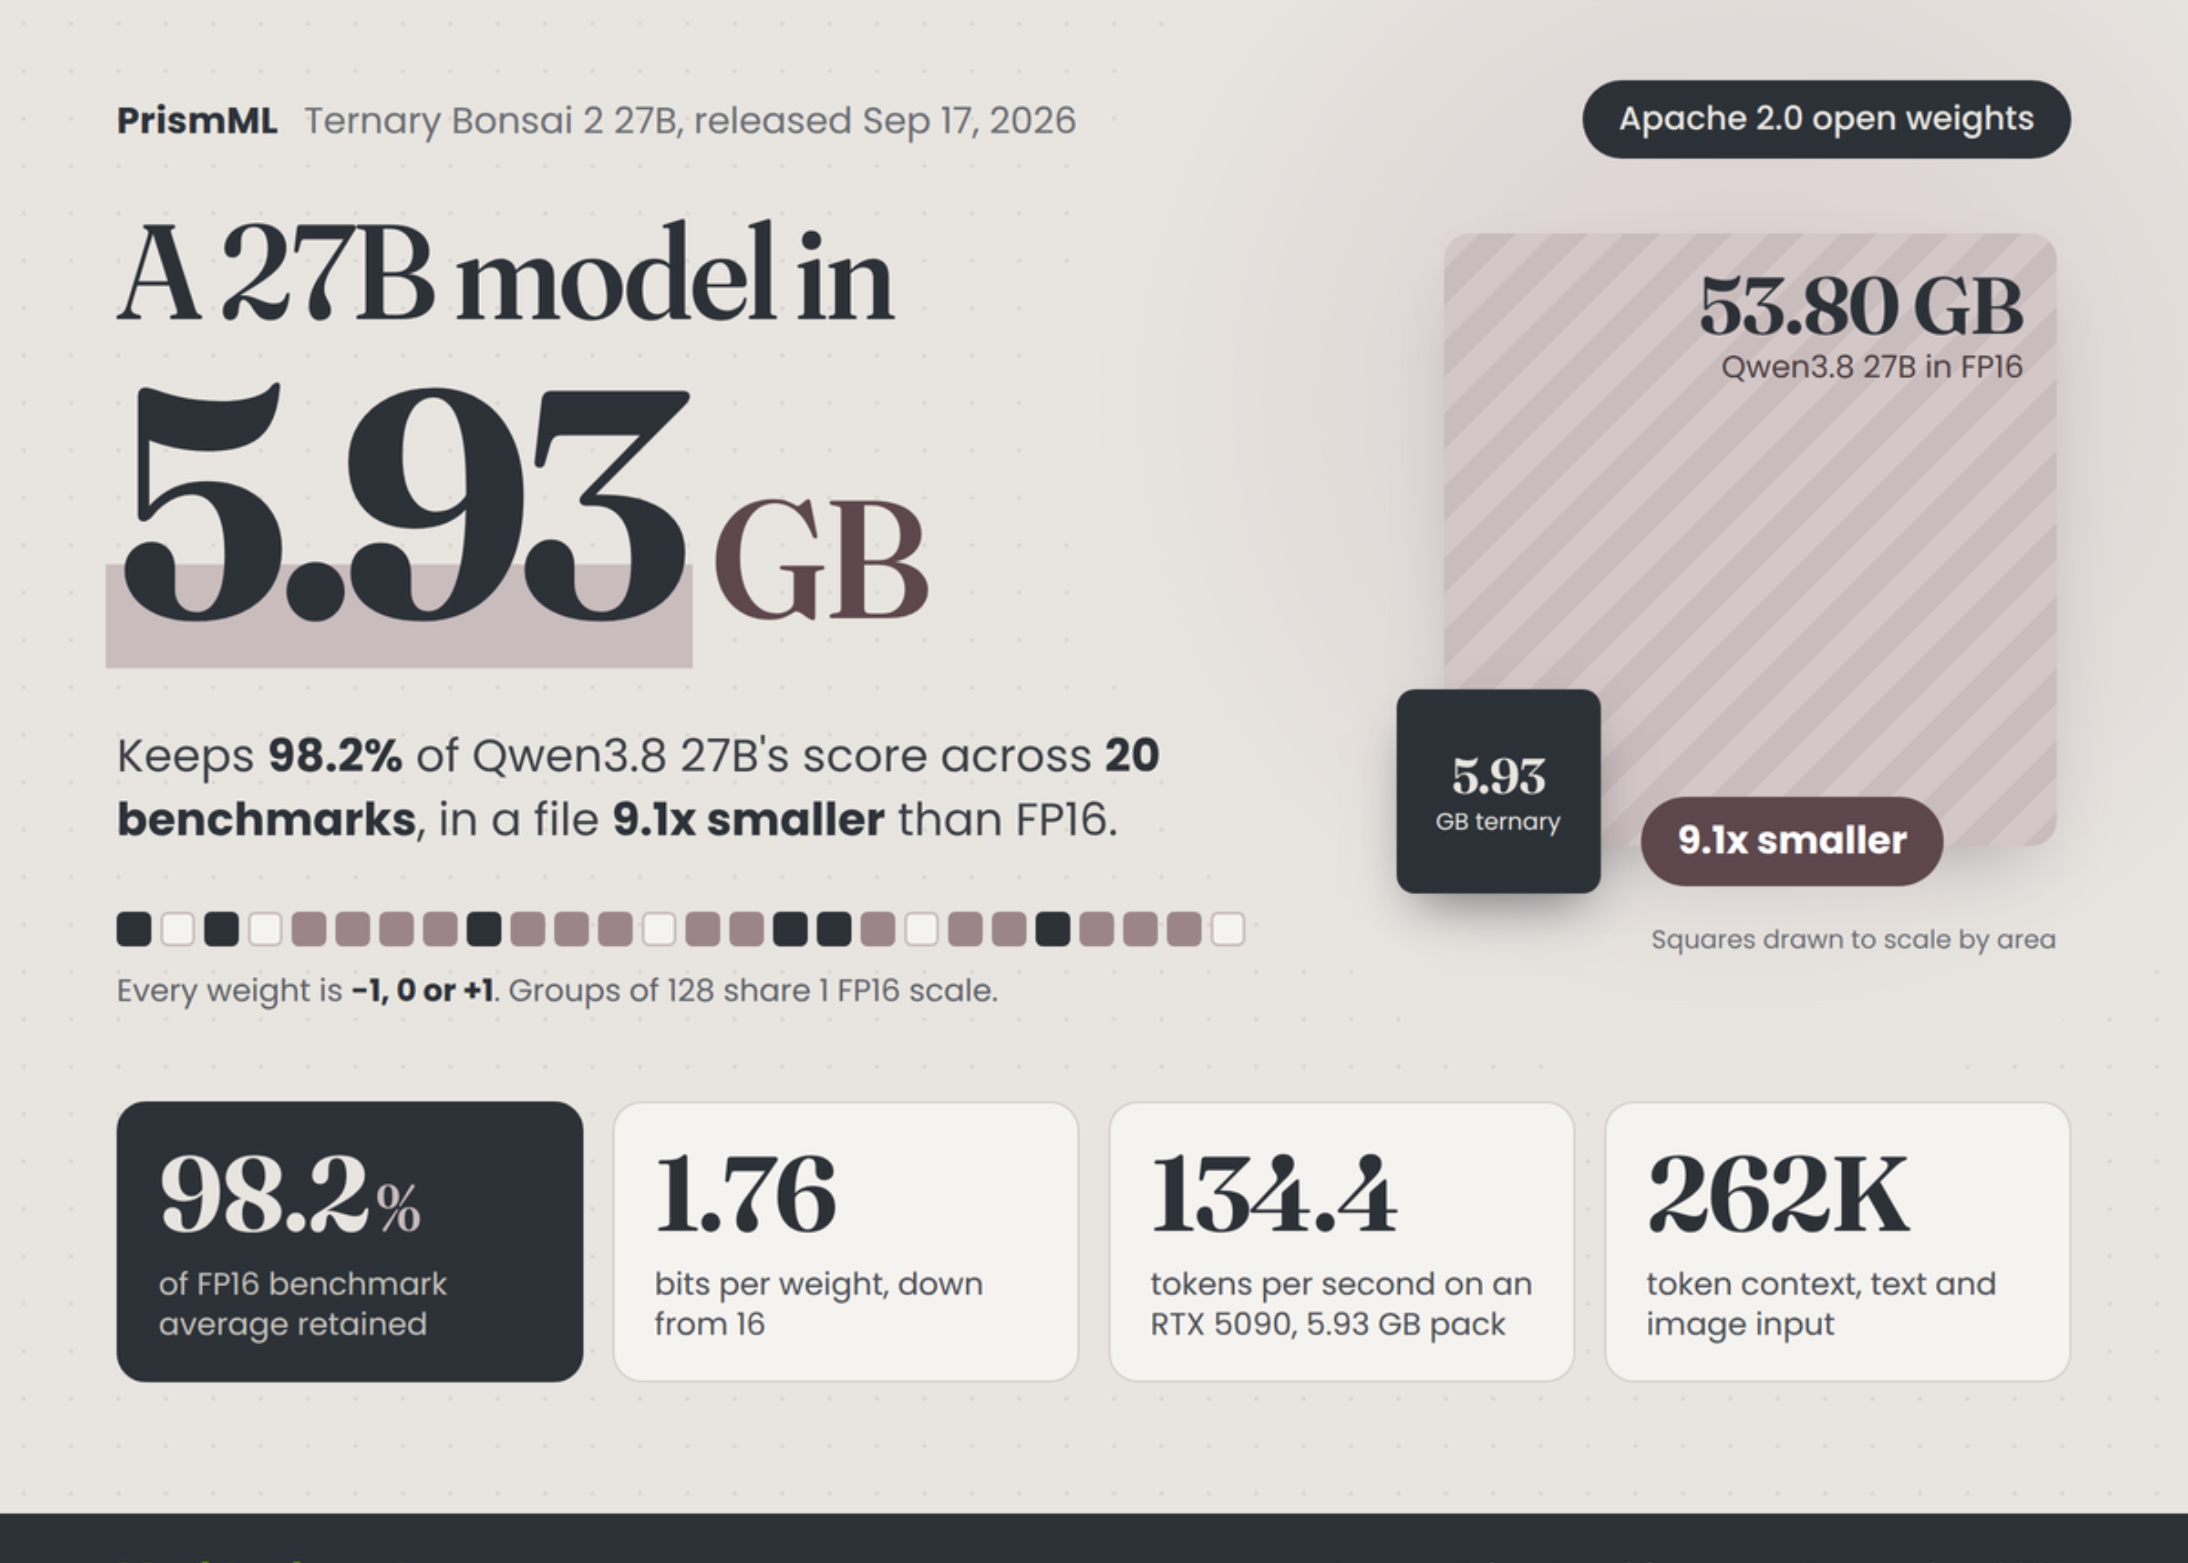
PrismML has released Ternary Bonsai 2 27B, a ternary-weight version of Qwen3.8 27B. The language model occupies 5.93 GB, against 53.80 GB in FP16. PrismML reports that it keeps 98.2% of the parent model’s average across 20 benchmarks. The model accepts text and images and supports a 262K-token context. PrismML demos it driving Cline coding agents and computer use on an RTX 5090. It arrives 2 months after the first Bonsai 27B, whose ternary variant retained about 95%.
Is it deployable? Yes. The Apache 2.0 weights run today on a 16 GB laptop or a single 24 GB GPU. You need PrismML’s llama.cpp fork or its MLX runtime.
What is Ternary Bonsai 2 27B?
The model keeps the Qwen3.8 27B architecture unchanged. It has 27.36B parameters. That splits into a 24.35B language backbone, 2.54B in embeddings and LM head, and a 0.47B vision tower. The backbone uses hybrid attention, with about 75% linear-attention and 25% full-attention layers.
Ternary weights cover embeddings, attention projections, MLP projections and the LM head. Only 26.2M parameters, or 0.0976%, stay in higher precision. Those are the recurrent state path and normalization weights. In GGUF, the vision tower ships separately as a 0.63 GB file, loaded only for image input.
How Does the Ternary Format Work?
Each weight takes 1 of 3 values: -1, 0 or +1. Every group of 128 weights shares 1 FP16 scale. A ternary value carries log2(3), or about 1.585 bits. Adding 16 scale bits per 128 weights gives 1.71 bits per weight. Counting the high-precision tensors brings the model to 1.72.
Real kernels need a packed layout, so the whitepaper describes 2 GGUF packings. PTQ1_0 packs trits densely at 1.76 bits per weight and 5.93 GB. PQ2_0 stores each trit in a 2-bit slot at 7.25 GB, which is cheaper to unpack.
Weights are also stored in a rotated basis. PrismML applies a blockwise Hadamard rotation with block size 1,024 before ternary assignment. The runtime applies the matching transform to activations before each multiply. The whitepaper cites SpinQuant for this idea. PrismML does not publish how it assigns the ternary values.
How Does It Score Against Qwen3.8 27B?
PrismML evaluated all models in thinking mode with EvalScope and vLLM on H100 GPUs.
The comparison with conventional quantization is the sharper result. An IQ2_XXS build of Qwen3.8 27B averages 75.2 at 7.3 GB. On AIME26 it scores 78.6, while Bonsai 2 scores 95.83. On LiveCodeBench v6 the gap is 70.05 versus 90.07.
Where Does It Still Lose Quality?
The 98.2% figure is an average, and the losses are uneven. Vision retains 96.3% and knowledge and reasoning retains 96.9%.
Long-horizon agent work drops further. Bonsai 2 scores 52.8 on Terminal-Bench 2.1, against 69.7 for Qwen3.8 27B. On SWE-bench Verified it scores 60.8 against 80.6. That is about 75% retention, and both sit outside the 20-benchmark average.
Reasoning effort matters too. At medium effort the model averages 79.3, against 82.6 for the FP16 baseline. Low effort is not supported. All results are PrismML’s own and have not been independently reproduced.
How Fast is It on Real Hardware?
Figures are batch size 1 decode on PrismML’s custom kernels, measured September 16, 2026. An RTX 5090 reaches 142.5 tokens per second at 0.582 mWh per token. An RTX 4090 reaches 96.7 with PTQ1_0, and a 72 W L4 reaches 32.1. On Apple laptops, an M5 Max reaches 46.8 and an M5 Pro reaches 27.7.
Neither packing wins everywhere. PTQ1_0 is faster on Ada-generation cards and the L4. PQ2_0 is faster on Blackwell, Hopper, Ampere and Apple silicon, and at prompt processing everywhere.
PrismML research team also claims 40% better energy efficiency than a full-precision 8B model.
How Do You Run It?
The GGUF files need PrismML’s llama.cpp fork. Stock llama.cpp rejects the PTQ1_0 and PQ2_0 types. The Bonsai-demo repo is the supported path. Run ./setup.sh, then ./scripts/start_llama_server.sh for chat, vision and tools at localhost:8080.
Mac users can take the MLX pack, which needs its bundled loader. A WebGPU demo runs the model inside a browser.
Key Takeaways
- 5.93 GB language model, about 9.1x smaller than the 53.80 GB FP16 baseline.
- 83.9 average on 20 benchmarks, versus 85.4 for Qwen3.8 27B in FP16.
- 142.5 tokens per second on an RTX 5090 and 46.8 on an M5 Max.
- Long-horizon agent benchmarks keep only about 75% of full-precision scores.
- Stock llama.cpp cannot load these files. PrismML’s fork is required.
Check out the Whitepaper, Model weights, GitHub repo, Docs, WebGPU demo and announcement on X. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.